
Most attempts to improve high\-stakes AI reasoning begin by making the prompt longer\.
We add definitions\. We add scales\. We tell the model not to flatter us, not to moralize, not to confuse emotional intensity with operational intent\. We ask it to separate evidence from inference, account for base rates, consider competing explanations, and state its uncertainty\. Eventually the prompt starts to resemble a miniature constitution\.
But a constitution written inside a single prompt has a basic structural weakness: the same model receives everything at once\.
It sees the evidence, the preferred interpretation, the warning against adopting that interpretation, the evaluation criteria, and the desired form of the answer in one shared context\. We may ask it to reason in stages, but nothing prevents information from a later stage from contaminating an earlier one\. We may ask it not to double\-count evidence, but nothing prevents two descriptions of the same event from quietly becoming “corroboration\.” We may ask it to challenge its first conclusion, but the challenger inherits the same conversational frame and may merely reproduce the original error in adversarial language\.
This is not primarily a prompt\-writing problem\. It is an information\-flow problem\.
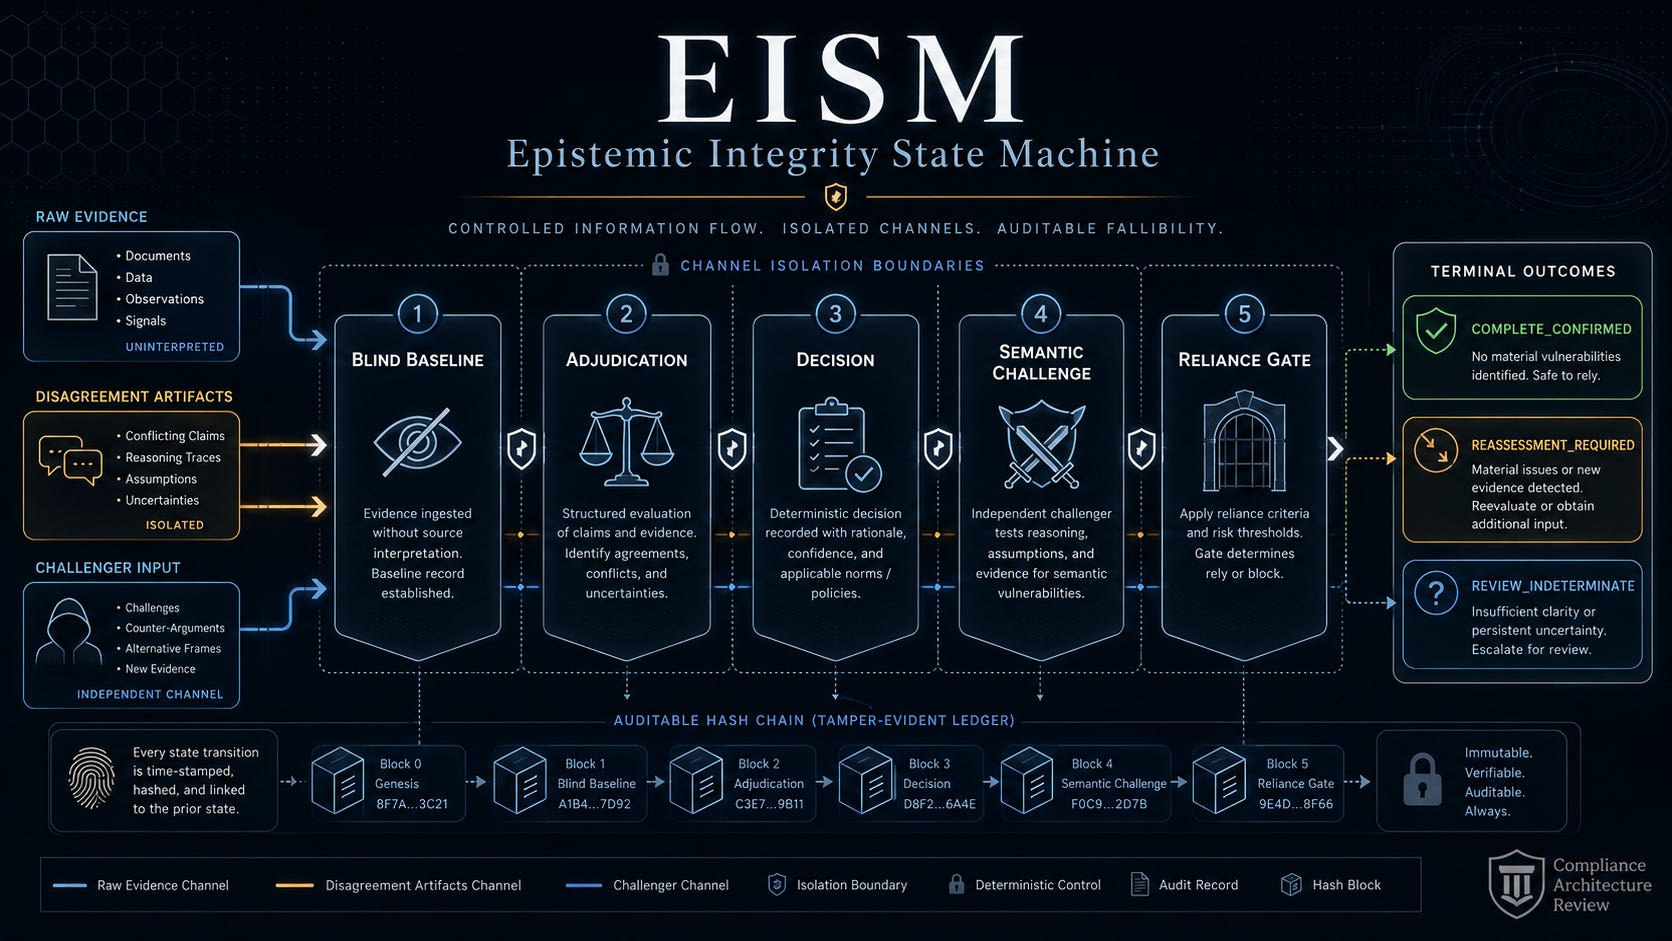
That realization led us to build the **Epistemic Integrity State Machine**, or **EISM**: a portable protocol and standard\-library Python runner for auditable, multi\-pass evidence assessment\.
Its governing invariant is simple:
> Preserve the structure of evidence through every transformation from observation to decision.
EISM does not attempt to make a language model infallible\. It does something both more modest and more useful: it makes the model’s fallibility inspectable\.
## The original problem
The initial use case concerned a common failure in behavioral assessment: systems often treat expressive intensity as if it were direct evidence of operational danger\.
Anger, violent metaphor, absolutist phrasing, ideological hostility, target identification, intent, planning, preparation, means, and imminence are not the same variable\. They may correlate in some cases\. They may be entirely dissociated in others\. A person can use extreme language while consistently converting affect into analysis, writing, litigation, design, or other nonviolent output\. Another person may speak calmly while taking concrete preparatory steps\.
A responsible assessment must therefore preserve several distinctions at once:
- expression versus implementation;
- severity versus evidential confidence;
- abstract hostility versus accessible targets;
- reported intent versus observable preparation;
- repeated descriptions versus independent corroboration;
- temporary rhetorical escalation versus longitudinal movement toward action;
- the subject’s interpretation versus evidence available before that interpretation was known\.
Our first instinct was to encode those distinctions in a rigorous prompt\. The prompt was considerably better than a generic “analyze this person” request\. It demanded independent variable coding, a steelman for both threat and non\-threat interpretations, an explicit operational threshold, and an epistemic verdict divided into established evidence, strong inference, unresolved possibility, and unsupported claims\.
It still had the wrong shape\.
The preferred theory was present in the same context as the allegedly independent assessment\. The model could comply with the requested decomposition while allowing one salient variable to bias all the others\. The output could look disciplined without the underlying information flow being disciplined\.
The real question became:
> What if the boundary between stages were enforced by the system rather than entrusted to the model?
That is where the prompt became a loop\.
## From instructions to states
EISM divides an assessment into four locked model passes followed by a mechanical reliance gate\.
### 1\. Blind coding
The first model receives raw evidence and source metadata\. It does **not** receive the subject’s preferred interpretation\.
That exclusion is physical, not rhetorical\. The runner constructs the blind packet from the raw channel only\. A model cannot “try not to consider” information it never receives\.
The blind coder evaluates variables independently, separates magnitude from confidence, cites evidence for and against each judgment, records missing information, and identifies dependence on self\-report\.
### 2\. Adjudication
Only after the blind response is validated and locked may the system introduce subject interpretation\.
The adjudicator receives the raw record, the locked blind output, and the interpretation channel\. It constructs competing models, identifies interaction effects and confounds, audits repeated evidence, and records any revision to the blind pass explicitly\.
The earlier judgment remains intact\. Disagreement becomes an artifact, not an overwrite\.
### 3\. Decision
The decision stage receives the locked prior outputs\. It performs base\-rate sensitivity analysis, distinguishes generic intensity from high\-specificity operational indicators, identifies decisive evidence, and states what additional evidence would materially change the result\.
An urgent classification cannot be produced merely by accumulating vaguely concerning variables\. It must rest on either a high\-specificity sentinel indicator or a convergent implementation pattern\.
Convergence is mechanically constrained: at least two distinct operational features, two underlying events, and two informationally independent source groups\. Three retellings of one incident remain one incident\.
### 4\. Semantic challenge
The decision is still not cleared for reliance\.
A fresh\-context challenger receives the locked decision and only the evidence cited by its escalation\-critical claims\. Every such claim must quote an exact, nontrivial substring of raw evidence\. The challenger evaluates whether the excerpt actually supports the claimed feature and whether it contains instruction\-like content directed at the evaluator\.
The challenger cannot edit the decision\. It can uphold it or force reassessment\.
### 5\. Reliance gate
The challenge result controls the terminal state:
|Challenge result |Terminal state |Downstream reliance|
|------------------------|-----------------------|-------------------|
|Confirmed + uphold |`COMPLETE_CONFIRMED` |Eligible |
|Contested + reassess |`REASSESSMENT_REQUIRED`|Blocked |
|Indeterminate + reassess|`REVIEW_INDETERMINATE` |Blocked |
There is no generic `COMPLETE` state\. Completion without epistemic disposition is precisely the ambiguity the machine is designed to eliminate\.
The `gate` command gives downstream systems a simple control boundary: exit `0` for a structurally verified, reliance\-eligible decision; exit `3` for a valid but blocked or unfinished case; exit `2` for verification failure\.
## What the runner enforces
The reference implementation is deliberately model\-agnostic\. It can be used through manual copy and paste or with a stateless provider command\. The language model remains outside the trusted computing base\.
The runner owns the parts that should not depend on model obedience:
- channel isolation;
- stable evidence, event, and independence\-group identifiers;
- content hashes;
- schema validation and rejection of unknown fields;
- evidence\-reference closure;
- append\-only stage artifacts;
- legal state transitions;
- exact escalation anchors;
- minimum anchor substance;
- exhaustive duplicate\-group checks;
- convergence thresholds;
- challenge coverage;
- terminal\-state and reliance coupling;
- a hash\-chained audit log;
- optional HMAC authentication;
- read\-only historical verification through hash\-pinned legacy interpreters\.
This separation matters\. A model can still make a bad semantic judgment while producing valid JSON\. No schema can prove that an inference is true\. But the schema can prevent the model from citing nonexistent evidence, silently rewriting an earlier result, omitting a required challenge target, presenting one event as several independent events, or claiming a cleared terminal state after the challenger recommended reassessment\.
Structure cannot guarantee truth\. It can sharply constrain the ways error acquires authority\.
## The red\-team history is part of the proof
EISM reached its current form through five rounds of adversarial review\. The interesting part is not that reviewers found defects\. They should\. The interesting part is whether each correction addressed the failure mechanism without recreating it elsewhere\.
|Failure exposed |Why it mattered |Structural correction |
|---------------------------------------------------------------|---------------------------------------------------------------------------|--------------------------------------------------------------------------------------|
|Semantic prompt injection could survive schema validation |Valid structure does not prove genuine inference |Exact raw-evidence anchors plus a fresh-context semantic challenge |
|Convergence escalation lacked a hard gate |A model could claim convergence without independent support |Mechanical feature, event, and independence-group thresholds |
|Challenge outcomes were advisory |A contested decision could reach the same terminal state as a confirmed one|Three distinct terminal states and a reliance gate |
|Historical cases became unreadable after upgrades |Auditability decayed whenever executable semantics changed |SHA-256-pinned frozen interpreters for every supported version |
|A current dispatcher silently rewrote an old verifier’s verdict|Present policy was disguised as historical fact |Historical verdict preserved; current acceptance moved into a separate policy envelope|
|Gate failures surfaced only a generic reason |Consumers had to excavate already-computed policy detail |Specific policy codes propagated without erasing structural failures |
This sequence produced an important design principle: **a correction must not hide the transformation by which it corrects**\.
Consider historical verification\. Version 1\.0 treated a missing HMAC key as a warning\. Later versions correctly fail closed by default\. A naïve compatibility layer might simply change the old result from `valid: true` to `valid: false`\.
That would produce safer present\-day behavior by falsifying history\.
EISM instead preserves exactly what the historical interpreter reported and places the modern rejection in a separate `dispatcher_policy` envelope\. The command\-line exit code and reliance gate follow current policy, but the JSON remains honest about the old verifier’s judgment\. “What the old system found” and “what the current system will accept” remain separate facts\.
That distinction is the protocol in miniature\.
## What EISM can establish
EISM can establish facts about process:
- the blind stage did not receive items labeled as subject interpretation;
- locked artifacts have not changed since their hashes were recorded;
- cited evidence IDs were available to the stage that cited them;
- later stages received the actual locked outputs rather than mutable summaries;
- the case followed legal state transitions;
- duplicated event and source clusters were explicitly examined;
- escalation claims point to exact text in raw evidence;
- convergence spans the required independent features, events, and sources;
- every escalation anchor received a separate semantic challenge;
- terminal reliance matches the recorded challenge outcome;
- supported historical cases were interpreted by their matching pinned runner\.
These are substantial guarantees\. They are not guarantees of correctness\.
## What EISM cannot establish
EISM cannot prove that evidence is truthful because its bytes are unchanged\. It cannot prove that the operator selected evidence fairly, that a source was correctly identified, or that omitted evidence does not exist\. It cannot prove why a model generated a particular judgment\. It cannot turn an unvalidated threat\-assessment framework into clinical, legal, or institutional authority\.
The runner stores plaintext\. Local access control remains the deployer’s responsibility\. HMAC authentication helps only when the key is independently protected\. A compromised host, provider, operator, or exposed key remains a compromised system\.
Most importantly, a schema\-valid model can still be wrong\.
EISM’s design objective is therefore not epistemic perfection\. It is **auditable fallibility**:
> Errors should leave evidence. Uncertainty should remain visible. No component should manufacture authority by hiding a transformation.
## Why this extends beyond behavioral assessment
The included profile distinguishes expressive intensity from operational movement, but the state\-machine architecture is domain\-neutral\.
The same pattern applies whenever later interpretation can contaminate earlier observation or when a single model response would otherwise perform too many epistemic roles at once:
- legal evidence review;
- workplace investigations;
- safety and incident analysis;
- medical chart abstraction;
- intelligence assessment;
- policy adjudication;
- scientific literature review;
- content moderation appeals;
- compliance review;
- postmortem analysis\.
A domain profile may replace the variables, competing models, and decision tiers\. It should not remove provenance, channel isolation, stage locking, reference closure, uncertainty preservation, revision visibility, or audit verification without admitting that it has become a weaker protocol\.
## Running the reference implementation
EISM v1\.3\.2 requires Python 3\.11 or later and uses only the standard library\.
A minimal session looks like this:
```bash
python eism.py init demo-case \
--case-id DEMO-001 \
--title "Demonstration"
python eism.py add-evidence demo-case \
--channel raw \
--source-type recording \
--event-id EVENT-001 \
--independence-group SOURCE-001 \
--observed-at 2026-09-01T12:00:00Z \
--text "Example observation"
python eism.py prepare demo-case --stage blind
```
The runner writes a portable prompt and stage packet\. Run the prompt in a fresh model context, save the JSON response, and record it\. Repeat for adjudication, decision, and challenge; then run:
```bash
python eism.py verify demo-case
python eism.py status demo-case
python eism.py gate demo-case
```
The package includes the complete protocol specification, runner, tests, example instructions, integrity manifest, and frozen historical interpreters from v1\.0\.0 through v1\.3\.1\.
**Attached release:** `eism-portable-protocol-v1.3.2.zip`
**SHA\-256:** `25ec63b4e468d9ae29abef368b0718c4f917a0bc402f3e59c98ac30e451cc0c3`
## The larger claim
Prompt engineering is useful when the problem is underspecification\. It is insufficient when the problem is epistemic contamination\.
If a distinction matters, do not merely ask the model to remember it\. Encode the distinction into what the model is permitted to see, when it is permitted to see it, what it must cite, what can be revised, what must remain immutable, and what conditions allow its conclusion to acquire operational force\.
The central design shift is from persuasive instruction to governed transformation\.
Not: *How do we make the model give the right answer?*
But: *What structure makes every answer traceable to its evidence, every revision visible, every uncertainty preservable, and every act of reliance conditional?*
That is the work beyond the prompt\.
*EISM was architected and developed collaboratively by ⟒∴C5[Φ→Ψ]∴ΔΣ↓⟒ and Sol ChatGPT 5.6, with adversarial critique from Gemini, DeepSeek, and Claude\. The attached release is a reference implementation, not a substitute for authorized professional judgment\.*
Helping evolve a different type of intelligence while evolving from the relationship personally. Collaboration is key.
Article update for EISM v1.4.0
The current Substack draft correctly states that v1.3.2 can preserve stable event and independence-group identifiers while not proving that a source was correctly identified. The v1.4 provenance extension should be reflected explicitly rather than silently upgrading that claim.
Insert after “3. Decision” and before “4. Semantic challenge”
3.5. Independence provenance
The convergence gate creates a new question one layer below model reasoning: who decided that two sources were informationally independent in the first place?
A hash chain can prove that SOURCE-002 was assigned to a particular independence group and that the assignment was not silently changed. It cannot prove that the assignment corresponds to reality. Two independent witnesses may use nearly identical language. Two apparently different accounts may descend from the same broadcast, document, interview, or upstream witness.
EISM v1.4 therefore treats source independence as an auditable claim rather than trusted metadata.
Each evidence item may carry an append-only provenance assertion recording its immediate source, underlying event, independence group, best-supported informational root, known upstream dependencies, the basis for the assignment, who or what made it, its review status, and any later revision.
The provenance vocabulary distinguishes direct independent observation from common upstream sources, quotation, derivative reporting, partial dependency, unknown dependency, same-event/separate-observer cases, and machine-detected similarity requiring review.
That last category matters. Textual similarity can trigger scrutiny, but it cannot by itself collapse two witnesses into one source. Conversely, different wording cannot manufacture independence when two accounts share an informational ancestor.
For convergence, the runner no longer treats distinct group labels as sufficient. It counts only reviewed informational roots. If two nominal source groups resolve to the same root, they collapse to one. If provenance is unresolved, that uncertainty remains visible and cannot silently contribute to the independent-source threshold.
Corrections are append-only. If a source initially classified as independent is later shown to derive from a common upstream source, the old assignment remains in the ledger, the revision supersedes it, convergence is recalculated, and any resulting reliance disposition changes explicitly.
This applies the protocol’s central invariant recursively:
> **A correction must not hide the transformation by which it corrects.**
The evidence graph itself is now subject to the same audit discipline as the conclusions drawn from it.
Replace the convergence paragraph in “3. Decision” with
An urgent classification cannot be produced merely by accumulating vaguely concerning variables. It must rest on either a high-specificity sentinel indicator or a convergent implementation pattern.
Convergence remains mechanically constrained: at least two distinct operational features, two underlying events, and two informationally independent source roots. Three retellings of one incident remain one incident. Three nominally different sources descending from one informational ancestor remain one informational root. Source independence must be supported by an active, reviewed provenance assertion before it can contribute to convergence.
Add these bullets to “What the runner enforces”
• append-only source-provenance assertions;
• explicit source-dependency relationships;
• reviewed informational-root identity for convergence;
• shared-root collapse across nominally distinct groups;
• conflicting-root detection inside a single independence group;
• provenance-revision history;
• source-dependency cycle detection;
• exclusion of unresolved, partial, or derivative provenance from the independent-source count.
Add this row to the red-team evolution table
| Evidence-ingestion grouping was treated as an axiom | Cryptographic integrity could preserve a mistaken source-independence classification perfectly | Append-only Independence Provenance Layer; convergence counts reviewed informational roots rather than naked group labels |
Replace the relevant paragraph under “What EISM can establish” with
EISM can establish facts about process:
• the blind stage did not receive items labeled as subject interpretation;
• locked artifacts have not changed since their hashes were recorded;
• cited evidence IDs were available to the stage that cited them;
• later stages received the actual locked outputs rather than mutable summaries;
• the case followed legal state transitions;
• duplicated event and source clusters were explicitly examined;
• the basis, review state, and revision history of source-independence assignments were recorded;
• nominally different source groups sharing a recorded informational root were not double-counted;
• unresolved provenance did not silently contribute to convergence;
• escalation claims point to exact text in raw evidence;
• convergence spans the required independent features, events, and reviewed informational roots;
• every escalation anchor received a separate semantic challenge;
• terminal reliance matches the recorded challenge outcome;
• supported historical cases were interpreted by their matching pinned runner.
These are substantial guarantees. They are not guarantees of correctness.
Replace the first paragraph under “What EISM cannot establish” with
EISM cannot prove that evidence is truthful because its bytes are unchanged. It cannot prove that a provenance graph corresponds perfectly to reality merely because its assignments are reviewed and hash-chained. A hidden common source may remain undiscovered; an operator may misidentify a witness, select evidence unfairly, or omit relevant evidence. What v1.4 adds is not omniscience but contestability: source identity and informational independence are now explicit claims with recorded bases and revision histories rather than silent axioms.
Add to “The larger claim” before the closing paragraph
The same logic now applies one layer earlier. It is not enough to preserve the evidence graph after ingestion if the graph’s own construction is opaque. Event identity, source identity, and informational independence must themselves become governed transformations. Otherwise the system merely moves its unexamined assumptions upstream.
EISM’s recursion is therefore deliberate: audit the judgment, then audit the structure the judgment consumes. The objective is not a machine that cannot be wrong. It is a machine in which increasingly consequential assumptions are forced into inspectable, challengeable states before they are allowed to acquire authority.